reef upgrade 2.2 to 2.7 - slow operations in bluestore
Hi, After a cephadm upgrade from 18.2.2 to 18.2.7 that worked perfectly, I am noticing lots ( 42 out of 161 OSDs ) "slow operations in bluestore" errors My cluster has all 3 types of OSDs ( NVME, SSD, HDD+ journaling) I found some articles mentioning below setting but it did not help Anyone else having this issue ? Thanks Steven bdev_enable_discard: "true" # quote bdev_async_discard_threads: "1" # quote
bdev_async_discard_threads more than 1 issue have been fixed at 18.2.7. pls use `top -H -p <osd pid>` observe osd thread cpu load, is there any abnormal situation? And what abnormal logs are there in osd log? Steven Vacaroaia <stef97@gmail.com> 于2025年5月13日周二 02:18写道:
Hi,
After a cephadm upgrade from 18.2.2 to 18.2.7 that worked perfectly, I am noticing lots ( 42 out of 161 OSDs ) "slow operations in bluestore" errors
My cluster has all 3 types of OSDs ( NVME, SSD, HDD+ journaling)
I found some articles mentioning below setting but it did not help
Anyone else having this issue ?
Thanks Steven
bdev_enable_discard: "true" # quote bdev_async_discard_threads: "1" # quote _______________________________________________ ceph-users mailing list -- ceph-users@ceph.io To unsubscribe send an email to ceph-users-leave@ceph.io
HI Steven, This issue has been around mailing lists since the new version came out: https://lists.ceph.io/hyperkitty/list/ceph-users@ceph.io/thread/S5XBS63NFIBJ... This is a new warning that can be adjusted or muted if uncomfortable but its advisable to check what’s causing this. We had a few warnings once upgraded to 19.2.2 and a single OSD restart vanished them away. Haven’t seen these warnings ever since. Best, Laimis J.
On 13 May 2025, at 06:55, yite gu <yitegu0@gmail.com> wrote:
bdev_async_discard_threads more than 1 issue have been fixed at 18.2.7. pls use `top -H -p <osd pid>` observe osd thread cpu load, is there any abnormal situation? And what abnormal logs are there in osd log?
Steven Vacaroaia <stef97@gmail.com> 于2025年5月13日周二 02:18写道:
Hi,
After a cephadm upgrade from 18.2.2 to 18.2.7 that worked perfectly, I am noticing lots ( 42 out of 161 OSDs ) "slow operations in bluestore" errors
My cluster has all 3 types of OSDs ( NVME, SSD, HDD+ journaling)
I found some articles mentioning below setting but it did not help
Anyone else having this issue ?
Thanks Steven
bdev_enable_discard: "true" # quote bdev_async_discard_threads: "1" # quote _______________________________________________ ceph-users mailing list -- ceph-users@ceph.io To unsubscribe send an email to ceph-users-leave@ceph.io
_______________________________________________ ceph-users mailing list -- ceph-users@ceph.io To unsubscribe send an email to ceph-users-leave@ceph.io
Hi, Thanks for your suggestions There is nothing significant in the log files expect "transitioning to stray" ( see attached) Restarting the daemons does not help as , after few minutes, they are complaining again ALL my HDD based OSDs on ALL 7 hosts are complaining [image: image.png] Steven On Tue, 13 May 2025 at 03:07, Laimis Juzeliūnas < laimis.juzeliunas@oxylabs.io> wrote:
HI Steven,
This issue has been around mailing lists since the new version came out:
https://lists.ceph.io/hyperkitty/list/ceph-users@ceph.io/thread/S5XBS63NFIBJ...
This is a new warning that can be adjusted or muted if uncomfortable but its advisable to check what’s causing this. We had a few warnings once upgraded to 19.2.2 and a single OSD restart vanished them away. Haven’t seen these warnings ever since.
Best, *Laimis J.*
On 13 May 2025, at 06:55, yite gu <yitegu0@gmail.com> wrote:
bdev_async_discard_threads more than 1 issue have been fixed at 18.2.7. pls use `top -H -p <osd pid>` observe osd thread cpu load, is there any abnormal situation? And what abnormal logs are there in osd log?
Steven Vacaroaia <stef97@gmail.com> 于2025年5月13日周二 02:18写道:
Hi,
After a cephadm upgrade from 18.2.2 to 18.2.7 that worked perfectly, I am noticing lots ( 42 out of 161 OSDs ) "slow operations in bluestore" errors
My cluster has all 3 types of OSDs ( NVME, SSD, HDD+ journaling)
I found some articles mentioning below setting but it did not help
Anyone else having this issue ?
Thanks Steven
bdev_enable_discard: "true" # quote bdev_async_discard_threads: "1" # quote _______________________________________________ ceph-users mailing list -- ceph-users@ceph.io To unsubscribe send an email to ceph-users-leave@ceph.io
_______________________________________________ ceph-users mailing list -- ceph-users@ceph.io To unsubscribe send an email to ceph-users-leave@ceph.io
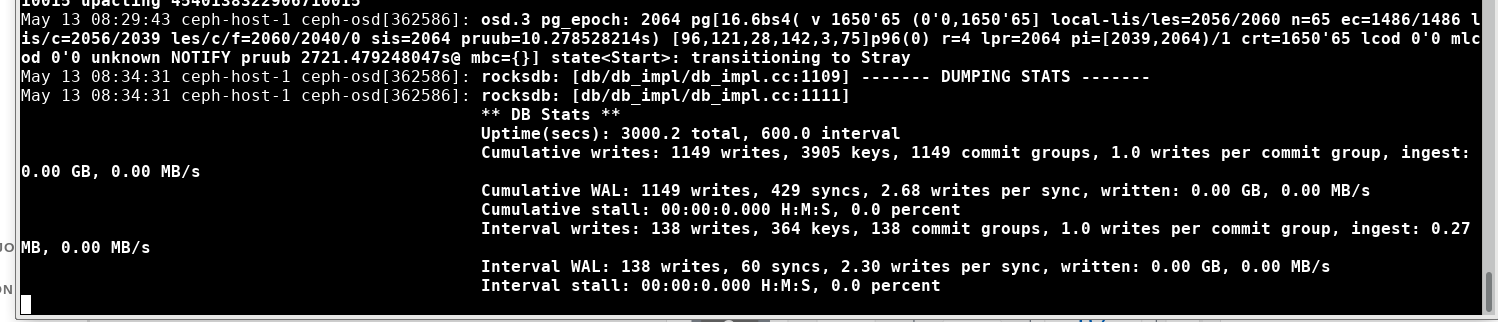
ALL my HDD based OSDs on ALL 7 hosts are complaining
Have you tried taking one OSD offline, compacting it, then restarting it? Also, what does your hardware look like? How many spinners per host? Do you have an IR (RAID) HBA, or a plain IT (JBOD) HBA? SAS or SATA? Internal WAL+DB or offloaded? Using hdparm / sdparm (or equivalent tool) to disable HDD volatile cache — at least when using a plain HBA — can make a distinct improvement in latency.
<image.png> Steven
On Tue, 13 May 2025 at 03:07, Laimis Juzeliūnas <laimis.juzeliunas@oxylabs.io <mailto:laimis.juzeliunas@oxylabs.io>> wrote:
HI Steven,
This issue has been around mailing lists since the new version came out: https://lists.ceph.io/hyperkitty/list/ceph-users@ceph.io/thread/S5XBS63NFIBJ...
This is a new warning that can be adjusted or muted if uncomfortable but its advisable to check what’s causing this. We had a few warnings once upgraded to 19.2.2 and a single OSD restart vanished them away. Haven’t seen these warnings ever since.
Best, Laimis J.
On 13 May 2025, at 06:55, yite gu <yitegu0@gmail.com <mailto:yitegu0@gmail.com>> wrote:
bdev_async_discard_threads more than 1 issue have been fixed at 18.2.7. pls use `top -H -p <osd pid>` observe osd thread cpu load, is there any abnormal situation? And what abnormal logs are there in osd log?
Steven Vacaroaia <stef97@gmail.com <mailto:stef97@gmail.com>> 于2025年5月13日周二 02:18写道:
Hi,
After a cephadm upgrade from 18.2.2 to 18.2.7 that worked perfectly, I am noticing lots ( 42 out of 161 OSDs ) "slow operations in bluestore" errors
My cluster has all 3 types of OSDs ( NVME, SSD, HDD+ journaling)
I found some articles mentioning below setting but it did not help
Anyone else having this issue ?
Thanks Steven
bdev_enable_discard: "true" # quote bdev_async_discard_threads: "1" # quote _______________________________________________ ceph-users mailing list -- ceph-users@ceph.io <mailto:ceph-users@ceph.io> To unsubscribe send an email to ceph-users-leave@ceph.io <mailto:ceph-users-leave@ceph.io>
_______________________________________________ ceph-users mailing list -- ceph-users@ceph.io <mailto:ceph-users@ceph.io> To unsubscribe send an email to ceph-users-leave@ceph.io <mailto:ceph-users-leave@ceph.io>
_______________________________________________ ceph-users mailing list -- ceph-users@ceph.io To unsubscribe send an email to ceph-users-leave@ceph.io
participants (4)
-
Anthony D'Atri
-
Laimis Juzeliūnas
-
Steven Vacaroaia
-
yite gu